
Resolve complex PGx regions
Long-read enrichment improves characterization of highly homologous genes, structural variants, and difficult genomic regions associated with drug response.
Alliance Long-Read PGx v2 Panel
Target pharmacogenomics genes using long-read sequencing
Enable comprehensive pharmacogenomics research with long-read target enrichment designed to resolve structurally complex genes and highly homologous regions. Optimized probe design supports accurate haplotyping, structural variant analysis, and detection of clinically relevant PGx markers that are difficult to characterize with short-read sequencing workflows. Compatible with long-read sequencing platforms for improved genomic resolution.
Long-read enrichment improves characterization of highly homologous genes, structural variants, and difficult genomic regions associated with drug response.
Supports phased variant analysis and haplotyping for improved pharmacogenomic interpretation and allele resolution.
Designed for compatibility with long-read sequencing platforms to maximize target coverage and sequencing efficiency.
Samples per ~30 Gb run*
Need mitochondrial coverage? Add the Twist Mitochondrial Panel.
*Assumes 30x mean target coverage with 50% off-target.
26 SNPs included to confirm sample identity across runs.
24 GeT-RM Coriell samples were sequenced on 1 SMRT® Cell 8M on the Sequel IIe system. Samples had on average 150k HiFi reads, with a mean read length of ~5.3 kb. Only 2% of duplicates were removed from downstream analysis. Across all targets, a mean target coverage of 190x was achieved. Across all samples, 96% of target regions exceeded 20x coverage and 93% of target regions exceeded 30x coverage.
Coverage of targeted regions (top track) showed great uniformity with no gaps, unlike short-read WGS data (bottom track) exhibited gaps and variable coverage.
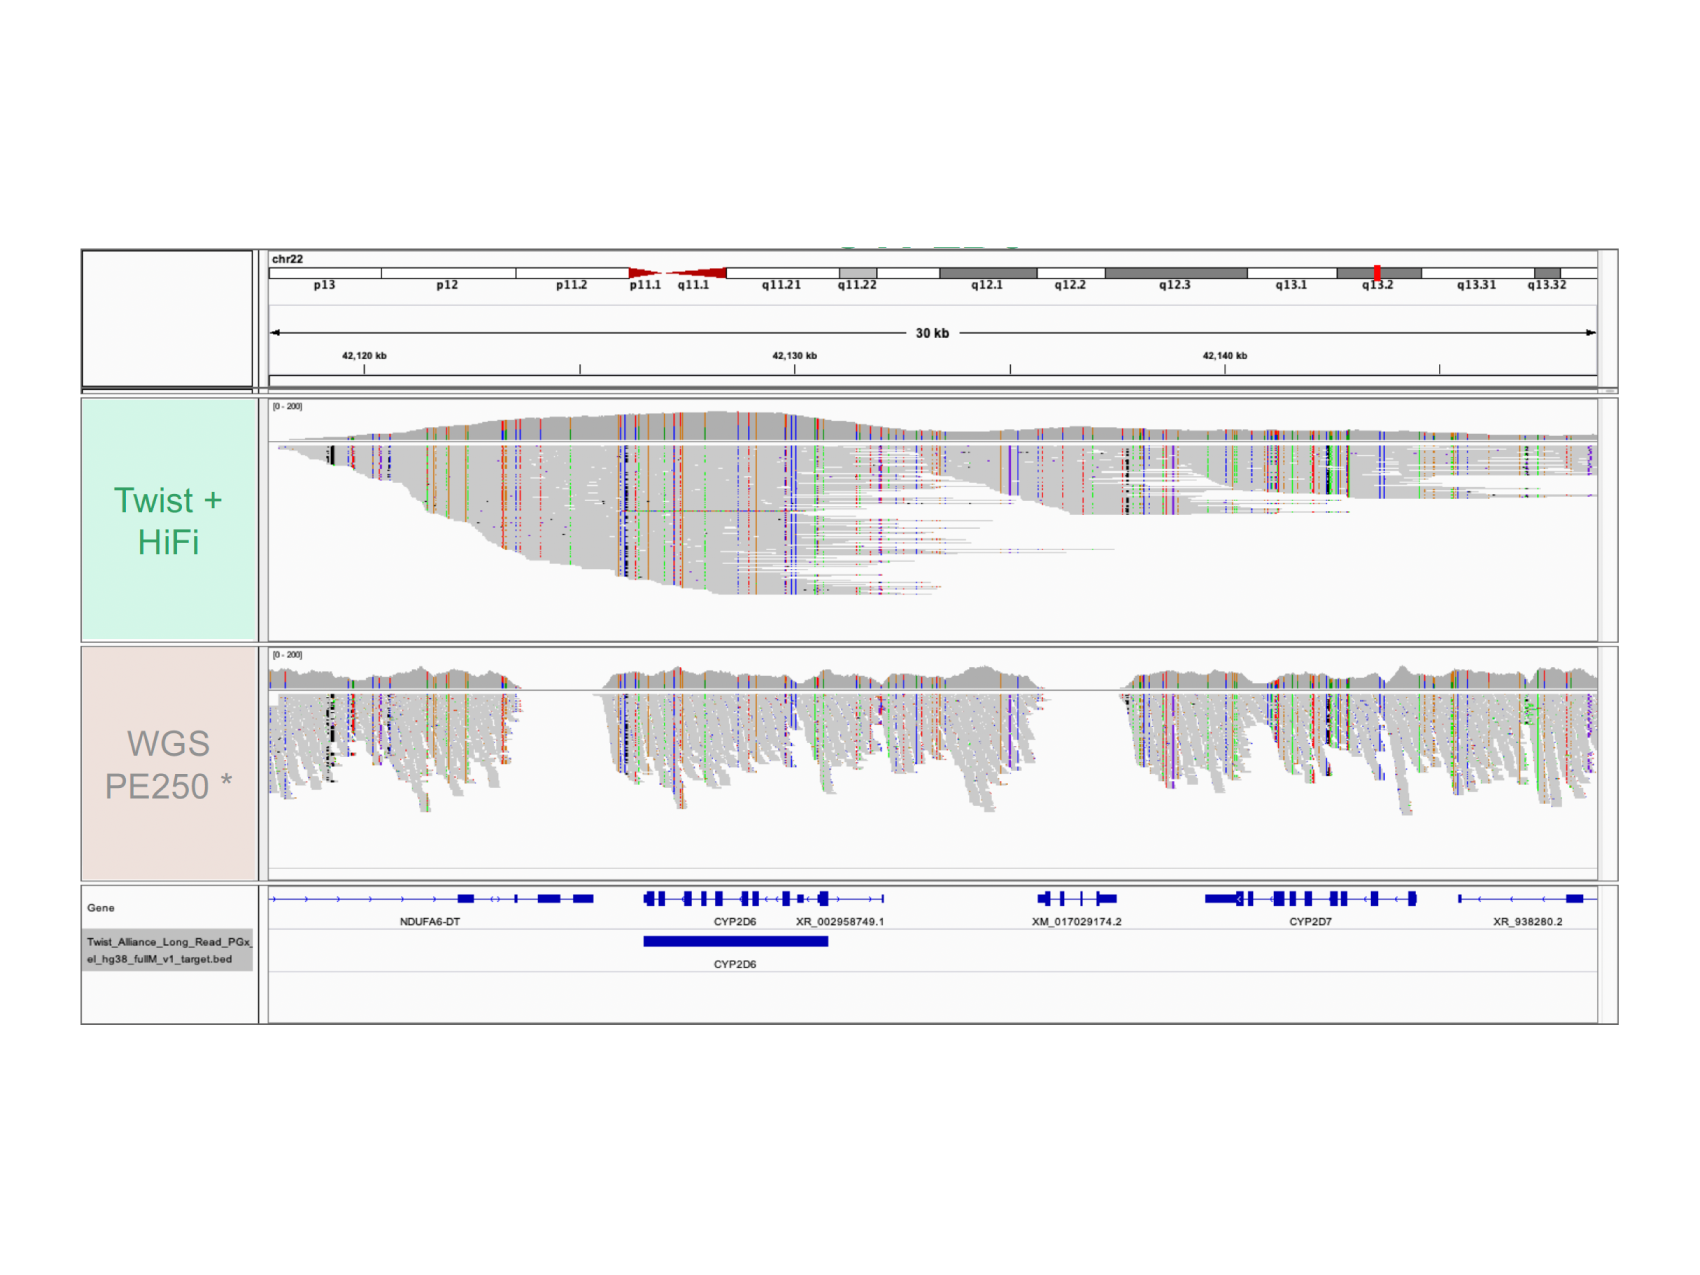
Figure 1. Target difficult-to-sequence, clinically relevant genes
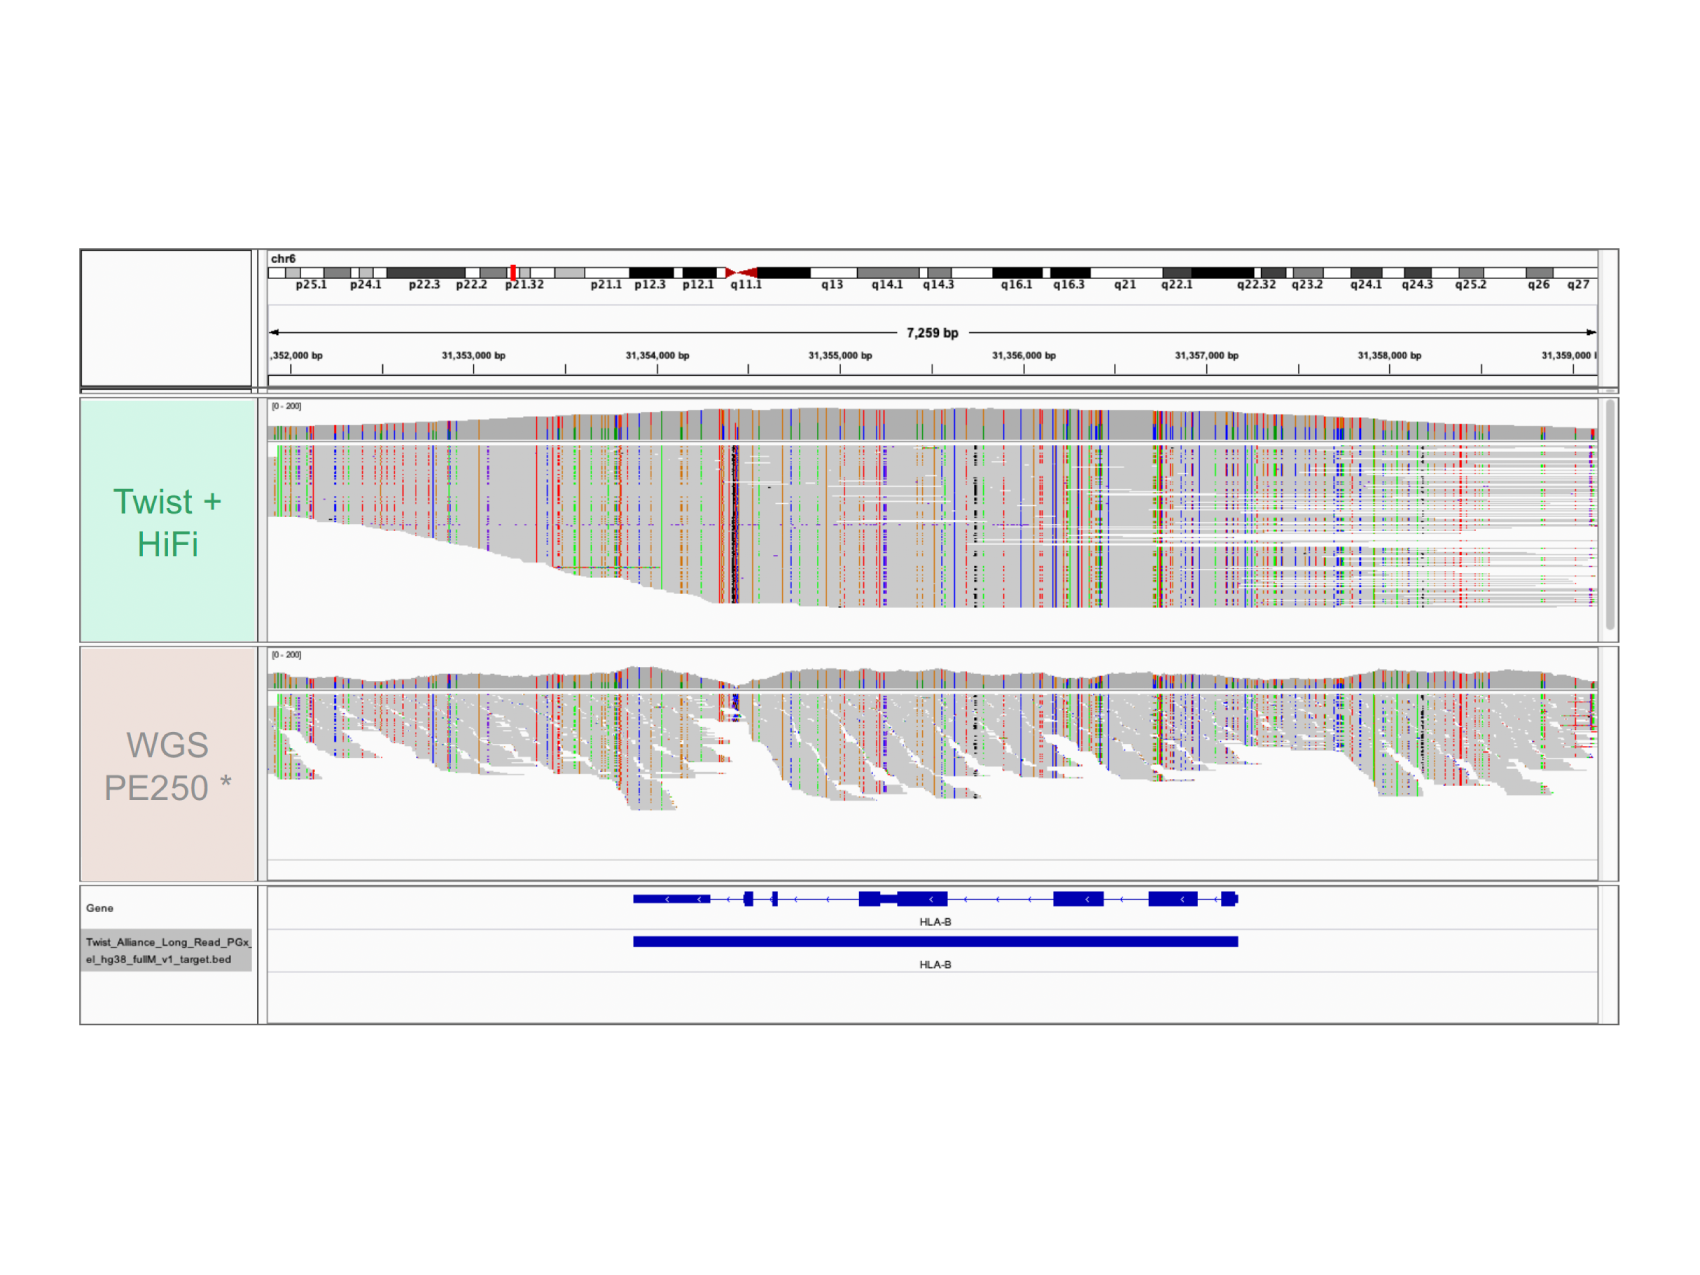
Figure 2. Deep coverage of target genes
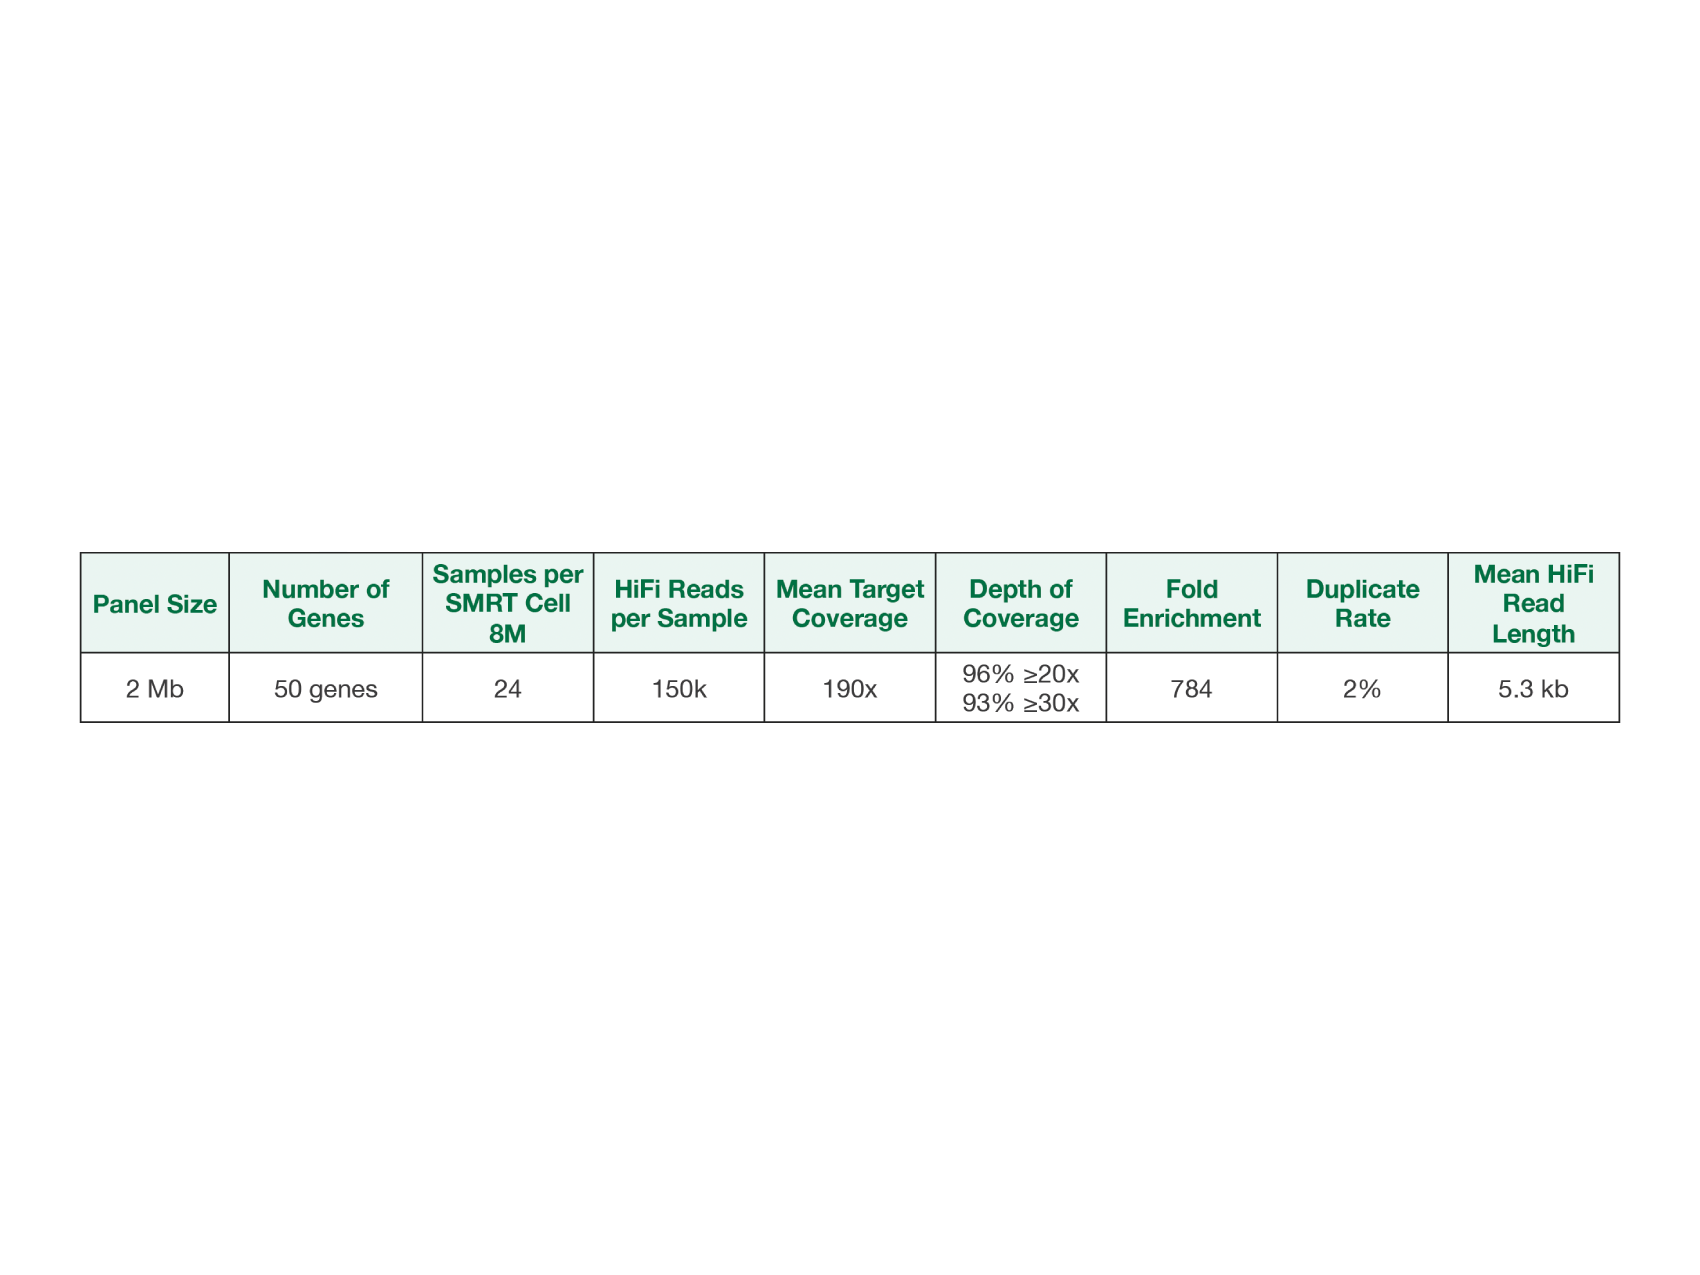
Figure 3. Uniform coverage with no gaps
Yes, Twist can design and build target enrichment which are completely custom, or can augment content to existing fixed panels. Contact your Twist account manager for more information.
The different read platforms are the (A) Target enrichment of libraries for exome sequencing of protein coding regions of the genome in which short reads tiled over the exomes are captured with biotinylated probes in hybridization capture. (B) Whole-genome sequencing in which the libraries are not enriched and therefore reads will tile across the input sequences. (C) Long read data which has much longer regions covered per read, which can also be paired with a biotin bait strategy to cover specific regions of the genome with long regions. (D) Linked read data in which the reads are barcoded in a way that enables you to identify the originating fragments and link their locations in an attempt to build up longer read regions.
Twist has validated Toyobo’s KOD Xtreme® Hot Start DNA Polymerase and Twist TrueAmp polymerase to work in the long-read protocol.
Need a specialist to boost your project?
Browse our FAQs for quick answers on our products and services or contact us to discuss your specific needs.
For Research Use Only.
Not for use in diagnostic procedures.
Trademarks: All trademarks, service marks, and registered trademarks mentioned herein—including GridION and Oxford Nanopore Technologies (Oxford Nanopore Technologies Limited); PacBio, Sequel, and SMRT (Pacific Biosciences of California, Inc.); Toyobo (TOYOBO CO., LTD.); and Novagen and MilliporeSigma (Merck KGaA, Darmstadt, Germany, or its affiliates)—are the property of their respective owners, and their inclusion does not imply any affiliation with, sponsorship by, or endorsement by them. KOD Xtreme Hot Start DNA Polymerase is manufactured by TOYOBO CO., LTD. and distributed under the Novagen brand by MilliporeSigma. GeT-RM and Coriell are referenced solely for identification purposes.

Twist Bioscience HQ
681 Gateway Blvd
South San Francisco, CA 94080